Precision cannot be emulated; it must be felt
Visual plausibility in robotics creates a dangerous illusion of competence; genuine dexterity requires massive scale grounded in tactile physical feedback.
When the agent thinks faster, the human thinks less
Offloading reasoning invites the human to skip not just the thinking but the validation that would catch its errors.
Every video cut lands on a neural deadline
Shot length, cut pacing, and response latency are not stylistic choices: each either meets the brain’s temporal expectations or violates them.
No Best Model for Image Editing
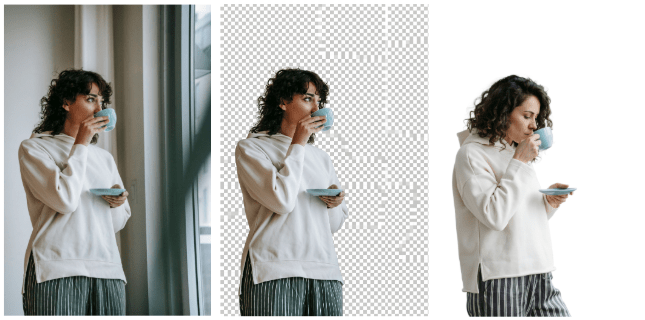
There is no such thing as “the best” generative model for editing. Image editing covers a broad spectrum of tasks with entirely different use cases, and correspondingly, different user expectations. An image editing task can entail removing a small defect from an image or could involve completely re-imagining a scene. What users expect of a generative image editing model for these tasks are entirely different outcomes, yet the common tendency in model evaluation and benchmarking is to collapse all cases into a single ranked set of models or objective functions.
Attention travels worse than the tools do
Someone creating or interacting with an AI tool on the go has far less mental room to spare than the same person at a desk; same AI tool, different outcomes.
Expertise begins with theory of mind
Modeling how someone thinks helps predict where errors will occur. But when that “someone” is an AI agent, behaviors can be independent and uncorrelated, complicating prediction.
Five or fewer feels instant
Humans can perceive up to four or five items instantly and accurately. Beyond that, the visual system switches to slower, effortful, serial processing.
Analogies expose real reasoning abilities
During model evaluations, analogies can stress-test cognitive depth: they require identifying structural relationships that remain constant when surface details change.
Paint your World: A Conversation with Generative Imaging Models
What’s in a generative model? A lot of judgement calls. These come through the training data that gets curated, labeled, and ingested; the reinforcement learning techniques and reward functions used to tune it; the mitigations that keep models in safe territories; and the prompt rewriting, reasoning loops, and inference-level parameter adjustments that are sometimes surfaced in the product and other times hidden from view. All these product and engineering decisions come together to mold the personality of the model that ends up in front of users. And these personalities start to show their faces once models are probed repeatedly across a broad set of subjects.
Today’s image models are getting closer to being true creative partners
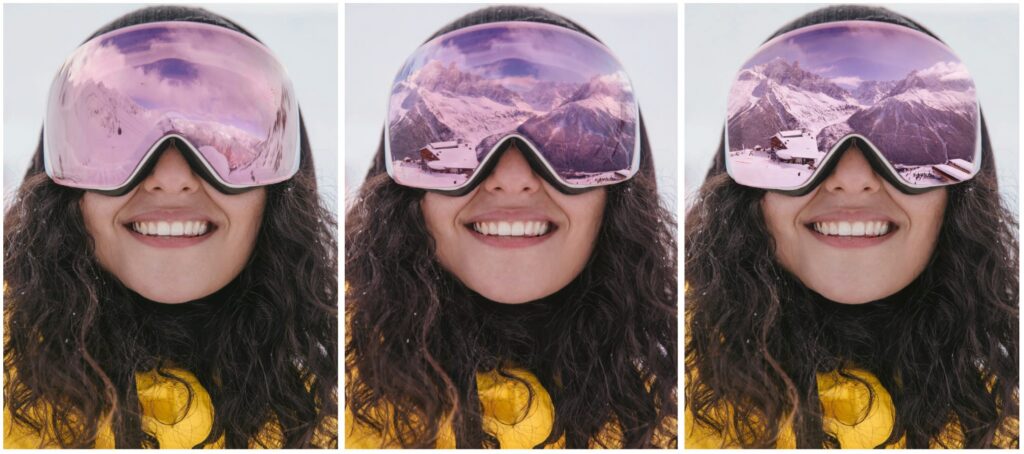
For the past few months, Piinc has been pushing new generative media models to their limits with image and video requests drawn from real creative workflows. Our goal is to evaluate whether models produce truly useful outputs: production-ready assets that need minimal to no further editing. Can these models understand user intentions out of the box, or do they need continuous prodding to reach the intended outcome? We’re not measuring whether outputs are generally likable – we’re assessing whether a model can be a good creative partner. And a good creative partner understands the user’s intentions and acts on them.